JST-2 Character: 3D characters with motion built in
One image in, a complete full-body 3D character out, ready to animate without separate rigging and skinning steps.
Viggle Research
This is the full character benchmark behind the JST-2 launch: how JST-2 builds characters with motion built in, how we tested them, and where they still fall short.
Key Takeaways#
- Characters with motion built in. JST-2 generates 3D characters from text or images with motion dynamics built in, so they are ready to animate without separate rigging and skinning steps.
- Complete characters from partial images. JST-2 generates complete characters from cropped or partially occluded images, across a wide range of visual styles.
- Ahead of both baselines. In blind tests against Meshy 7.1 and Tripo H3.1, JST-2 leads on character generation, with its strongest results on facial detail, and on animation readiness, particularly in hand articulation and in how the body and clothing deform during motion.
Characters with motion built in#
JST, short for Joint Space-and-Time, models the world as persistent atoms in 3D space. Each atom represents a piece of matter or an object part and retains its identity as it moves and deforms. It has an explicit xyz position and learned vectors for its attributes and dynamics. We encode these atoms as Physics-Native Tokens, and the JST decoder turns them into 3D Gaussian splats.
A JST-2 character is built from these tokens. The dynamics vectors in its Physics-Native Tokens encode how each part deforms under different motions. These dynamics are learned from data, so a character is ready to animate without separate rigging and skinning steps. In a conventional animation or game pipeline, rigging and skinning are specialist work measured in hours, and the rig decides how the character moves for the rest of its life. JST-2 builds the character and its motion dynamics in one generation.
JST-2 can also generate complete characters from cropped or partially occluded images, across a wide range of visual styles. Real inputs are not studio plates: lighting, angle, framing and occlusion are all over the place. When only the upper body is in frame, when the subject is turned away, or when hands and feet are hidden, JST-2 completes the rest into a body whose structure and proportions hold together.
How we evaluated JST-2#
Human evaluators compared JST-2 with Meshy 7.1 and Tripo H3.1 in blind tests. Every model saw the same input images, and every asset was generated in batch through each vendor's own API, as close to a production run as we could get.
We tested two things. Character generation is the visual quality of the full-body character built from one image. Animation readiness is how each model's generated character moves once it is driven.
The test set follows the category breakdown used by the major commercial 3D asset platforms (photoreal, stylized, cartoon, anime, sci-fi) and adds hard samples drawn from what users actually upload: unusual poses, occluded subjects, off-axis viewpoints, bodies cropped out of frame, difficult lighting, low-resolution and blurred images, and busy backgrounds.
Average Score is the equal-weight mean of all criteria, including Overall Preference. Draws count as half a win. A score of 50% indicates equal preference between JST-2 and the comparison model.
Character generation#
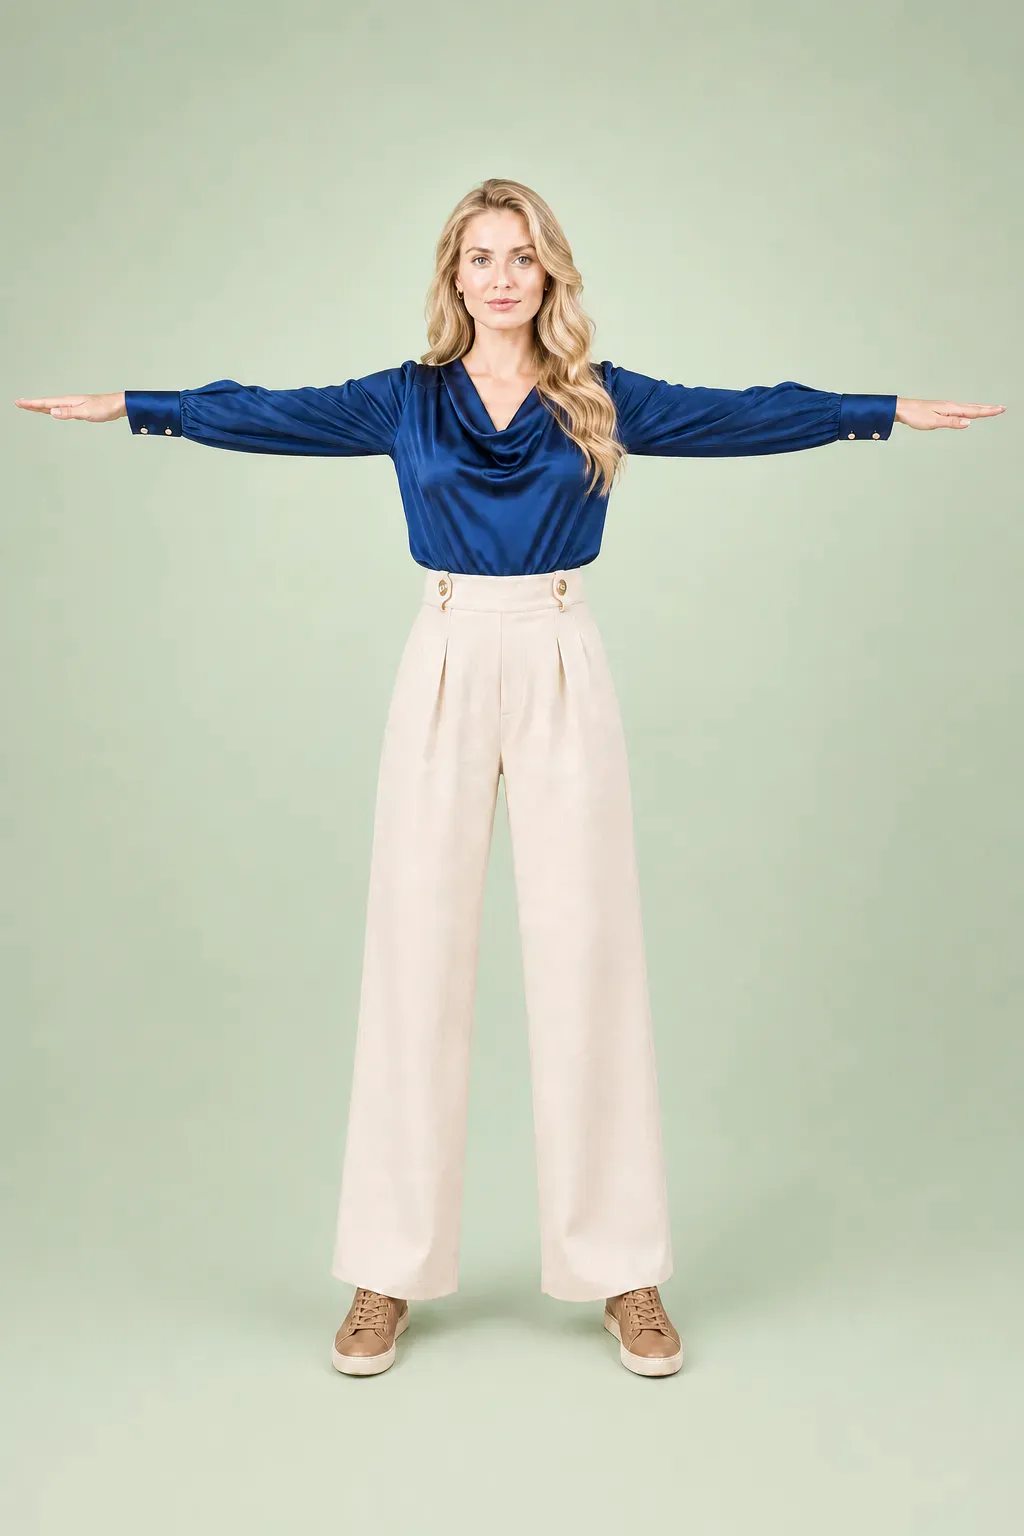
JST-2 generates 3D characters from a single image, ready to animate without a separate rigging step.
JST-2 leads both baselines on character generation, with its strongest results on facial detail. These details help preserve the character's identity in 3D, whether that is your own digital double, an actor's stand-in, or an IP character you will reuse for years.
vs Meshy 7.1
vs Tripo H3.1
JST-2 does not stop at the visible region. When only the upper body is in frame, when the subject is turned away, or when hands and feet are behind something, it completes the rest into a body whose structure and proportions hold together. On clean images all three models are usable; the gap opens on difficult ones, and real creative work rarely starts from a clean image.
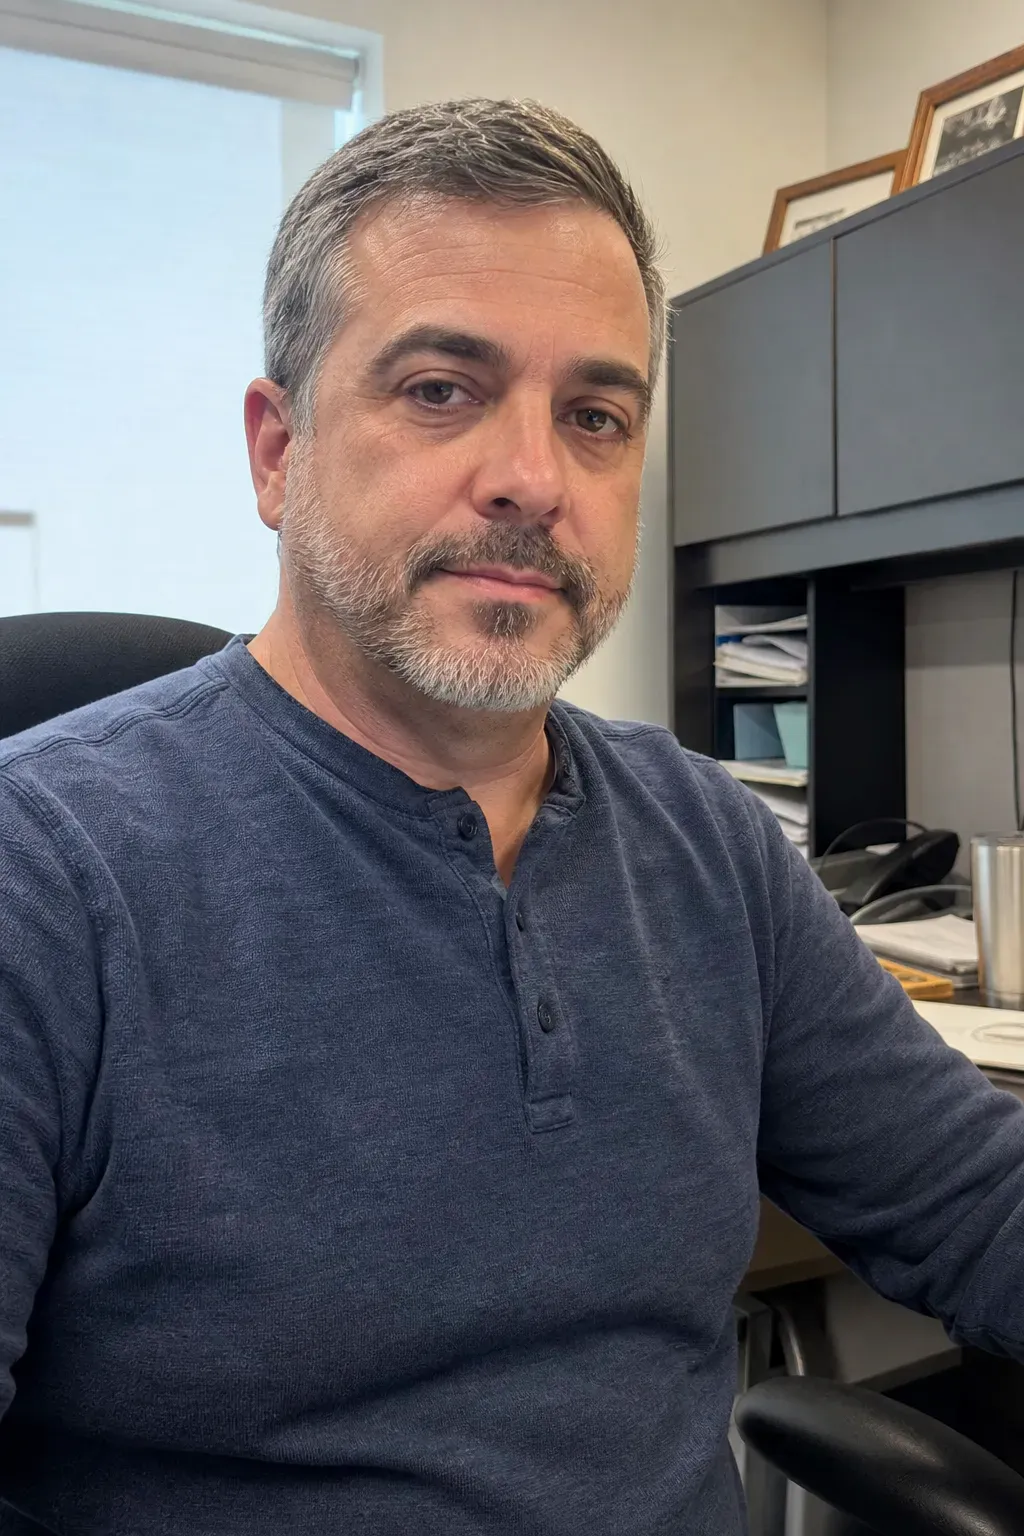
Characters generated from hard inputs. Source images generated with GPT Image 2.
Animation readiness#
To evaluate animation readiness, we compared how each model's generated characters move. JST-2 leads both baselines, particularly in hand articulation and how the body and clothing deform during motion. Every finger moves on its own, and once the character moves, clothing, hair and accessories deform with the body rather than fighting it.
vs Meshy 7.1
vs Tripo H3.1
All of it happens in a single generation: complete body, 3D character and motion dynamics at once, with no remesh and no separate rigging step left for the user.
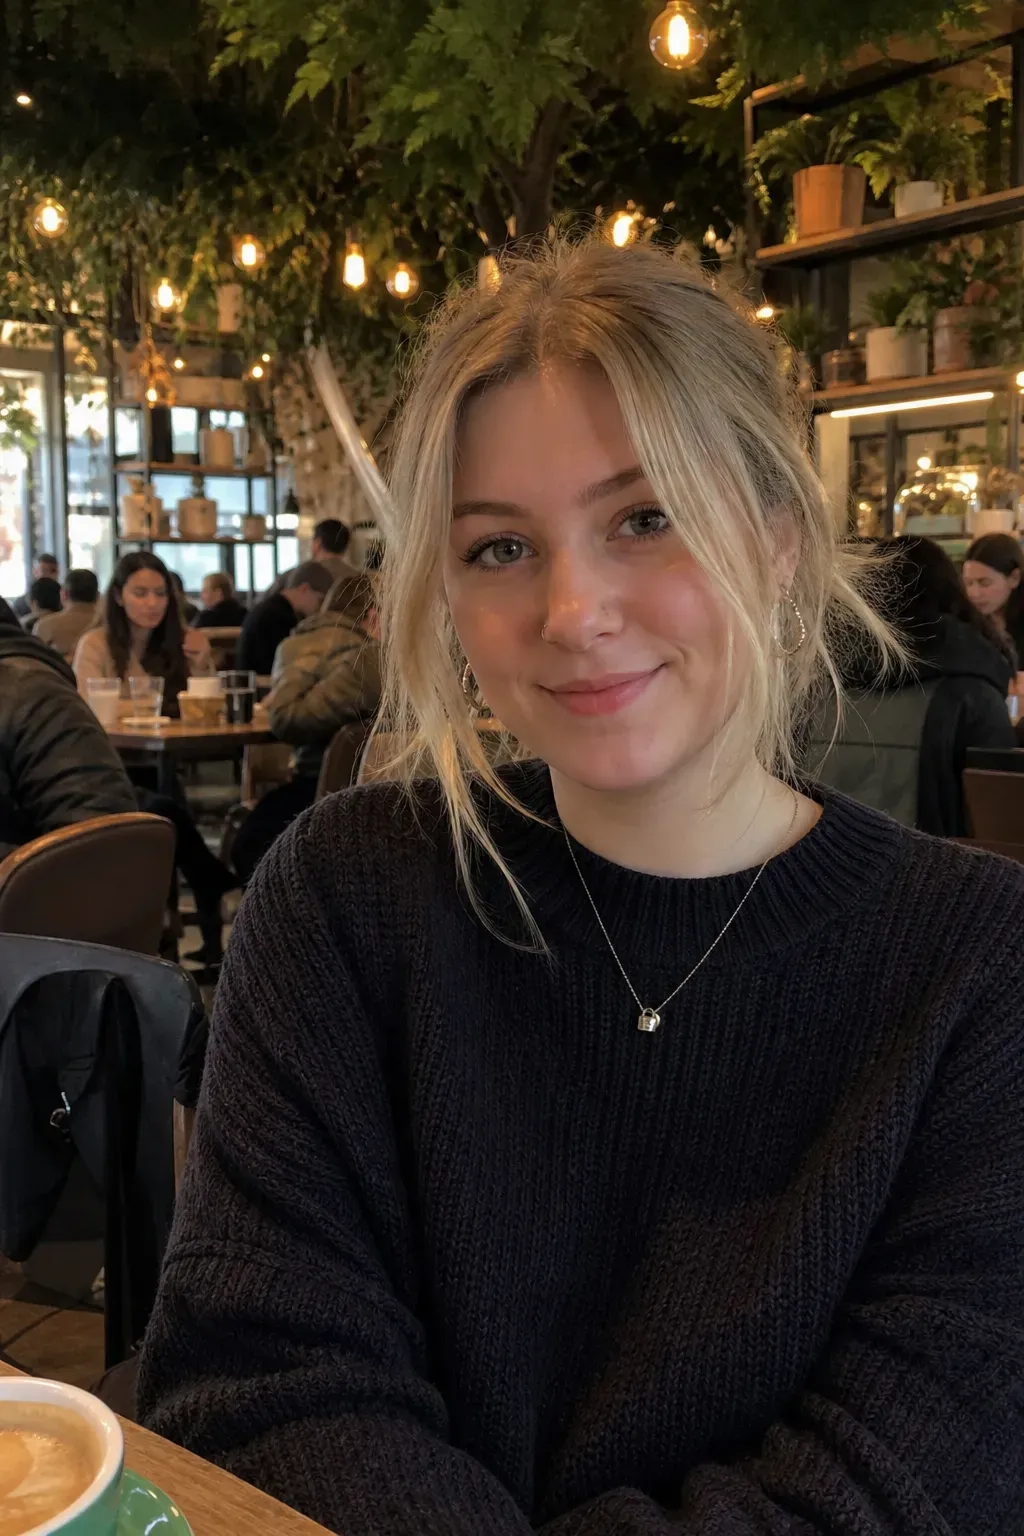
Animated characters generated from hard inputs. Source images generated with GPT Image 2.
What comes next#
Upcoming releases will improve how complex clothing deforms during motion and how hair moves. Today a few limits remain.
Gaussian artefacts around limb joints. In some cases the shoulder-to-torso join, the armpit and the gaps between fingers show holes, merging or collapse. It is the most visible failure mode.
Surface detail has a ceiling. Hair, clothing and materials read cleanly at normal viewing distance, but soften as the camera moves in.
Unusual bodies. When a body departs from normal human proportions (very long limbs, an exaggerated head-to-body ratio, a non-humanoid silhouette), joint placement and deformation can both be off.
Learned physics is the next step. Clothing, hair and accessories deform with the body but are not simulated: they do not swing from inertia or collide with the body or with each other. In JST-2, character motion is driven by learned dynamics. Scene collisions and object interactions still rely on rule-based physics. We are developing JST-3 to replace those rules with learned dynamics that predict how objects interact and how those interactions change the world.
Read the JST-2 launch